Human Gap report #1: the counter says zero, and that is the starting line
Baseline read of HIM's public Human Gap counter on 23 Oct 2026: 12,516 items measured, 1,187 missed by our AI attacker, 0 human answers, 0 gold.
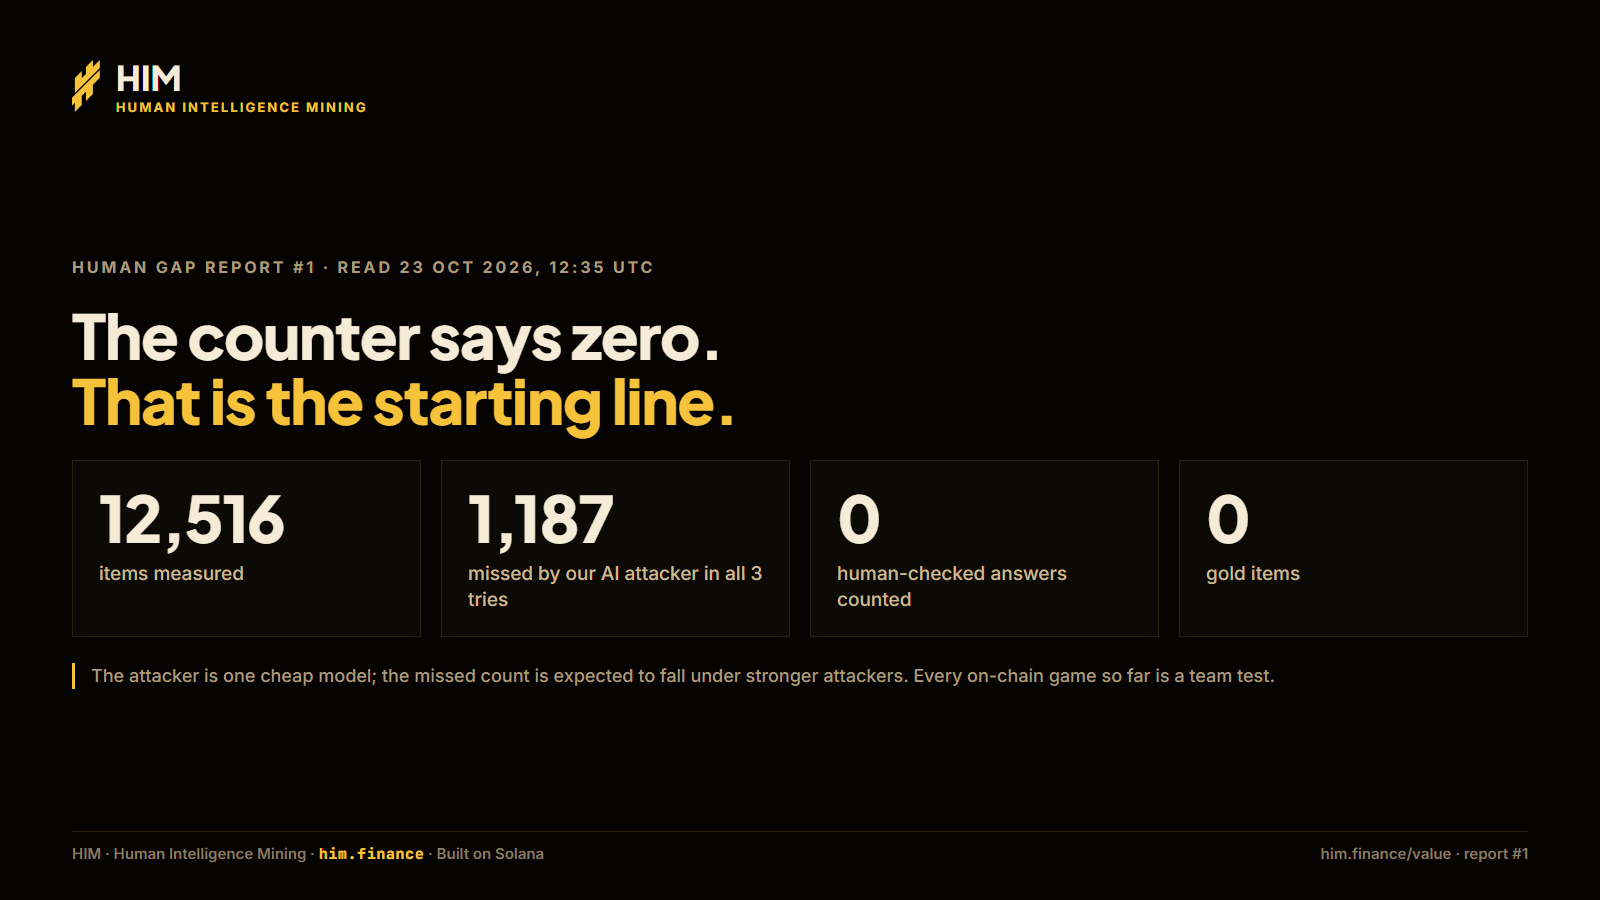
Most launch reports open with a big number. Ours opens with two zeros.
On 23 October 2026, HIM's public Human Gap counter showed 0 human-checked answers counted and 0 gold items. We are publishing that anyway, and we will keep publishing it every week, because a counter that only appears once it looks good is not a measurement. It is marketing.
This is report #1. It sets the baseline: what the counter measures, what it read on the first day we wrote down, and what the next weeks have to show.
What we measured (baseline)
Read from the public counter behind him.finance/value on 23 October 2026 at 12:35 UTC:
Counter Value Items measured 12,516 Missed by our AI attacker in all three tries 1,187 (9.5% of measured) Human-checked answers counted 0 Gold items 0 Silver items 0 Previous read, 22 October 2026, about 15:10 UTC: 12,011 measured, 1,122 missed, 0 human-checked answers, 0 gold.
Proof Seal signer on Solana mainnet, read 23 October 2026 at 12:37 UTC: 94 seal-signer signatures since 8 Oct 2026, 0 failed.
What the counter is
The Human Gap is the distance, on one question, between what people know and what an AI gets right. We keep it as one number per item:
AI Gap = share of people who answer it right − share of AI tries that answer it right.
The counter at him.finance/value shows the running state of that work in four numbers. It shows numbers only. There is no price on the page, and no claim about what any of this is worth.
Items measured
An item is one question with its answer options. "Measured" means our AI attacker has already played it. On 23 October that was 12,516 items across the topic banks currently in play.
Missed by our AI attacker
Every new item gets three tries from one cheap, text-only model before it counts as measured. If the model gets it wrong all three times, the item is marked AI-missed. On 23 October that was 1,187 items, about 9.5% of those measured.
That share sounds small. It is small. In a separate test, the same kind of cheap model answered 255 of 260 sampled HIM questions as a plain quiz (98.1%). Most questions a person can write, a model can answer. The AI-missed items are the minority that make the rest of the work worth doing.
Human-checked answers
This is the number that matters most and the one that reads zero. It counts answers from players who passed a short human check, given inside HIM's game mechanics on a clock the server keeps. Without those answers, an AI-missed item is only half measured: we know the machine got it wrong, but not whether people get it right.
Gold
An item becomes gold when people are ahead of the AI by at least 30 points on it, measured over at least 30 human-checked answers inside an eight-week window. These are the settings the counter itself publishes, and we may change them as we learn; if we do, the change will be dated in the next report. There are no gold items yet, because there are no counted human answers yet. Silver also reads zero.
Why the human side is at zero
The plain reason: hardly anyone outside the team has played yet.
Outside traction is about zero: every on-chain game so far is a team test, 0 human-checked answers have been counted and there is 0 gold. Revenue is about $0.
We could have waited for the first few hundred players before turning the counter on. We decided not to. If we only start counting once the numbers look good, nobody can tell which part of the curve was real. Starting at zero, on a public page, with dated reads, is the only way the later numbers mean anything.
What moved between the two reads
Between the 22 October read and the 23 October read, the measured count went from 12,011 to 12,516 (+505 items) and the AI-missed count went from 1,122 to 1,187 (+65). That is the AI side of the pipeline doing its job: new items arrive, the attacker plays each one three times, and the small share it misses is set aside.
The cost of this side is close to nothing. We scored 24,042 items with ~72,000 AI attempts for $0.96 (HIM internal measurement, Oct 2026). That one-off backfill covered a wider set than the counter's current scope, which is why the two totals differ.
Measuring the machine is cheap. Measuring people is the expensive, slow part, and it is the only part that cannot be done by us alone.
What a seal adds
Each question set is committed on Solana before it can be drawn, and settled results are committed after. The latest seal the counter links to was written to Solana mainnet on 23 October 2026 at 08:01 UTC. Across the signer's history: 94 seal-signer signatures since 8 Oct 2026, 0 failed (read 23 Oct 2026).
A seal has limits, and we would rather state them than have someone discover them. Free Token Rain and free Quiz are not sealed. Paid Ball is sealed after only. The first result seals were our own test rounds. A seal shows that nothing changed after the commitment; it does not show that the server never read an answer.
If you want to check a round yourself, the open-source verifier compares it against the chain. It passed a real mainnet league round with 39 checks.
What the next weeks have to show
Here is what we will look at, in the order we expect it to happen. Each report will give the same table with a new date.
- The first human-checked answers. Any number above zero tells us the path from sign-in, through the short human check, to a counted answer works for people who are not on the team.
- The first items to reach 30 human answers. Thirty is the minimum before an item can be judged. The first items to get there will most likely be easy ones, played often.
- What people do with the AI-missed items. This is the real test. Some AI-missed items will turn out to be well known to people: that is the gap. Others will turn out to be badly written or plainly wrong, and people will miss them too. We expect both, and we will report both.
- The first gold item, if one appears. We are not promising one by any date. Gold needs enough human answers on the right items, and that depends on how many people play.
- A stronger attacker. The missed count comes from one cheap model. It is expected to fall under stronger attackers. If we add one, we will show both numbers side by side rather than quietly swapping one for the other.
What we will not do in these reports
- We will not round a zero up, or show a "community" number that is really the team.
- We will not put a price or a value on items.
- We will not change a rule without saying when and why.
- We will not use the words "proof" or "verified" for people. A short human check is a check, not a passport.
How you move the counter
The counter is waiting for one thing: people answering questions after a short human check.
Here is the path. Sign in at him.finance. Connect a wallet with one signature: no transaction and no fee. Pass the short human check. Then play today's round. The questions run inside a game, the clock is the same for everyone, and at the end you will see a gold mark next to every question you knew that the AI missed in all three tries.
Then send the round to someone who thinks they know more than you. From your result screen, a challenge link lets them play the same questions against your recorded run. Nothing is paid for sharing it. But every second person who answers the same item is exactly what this counter needs: an AI-missed question only becomes interesting once enough humans have tried it.
Report #2 follows next Monday, with the same table and a new date.